

Last night I continued a project I started three months ago: Moving my websites off an aging Linux virtual private server that kept going offline and getting overwhelmed, mainly due to bot traffic. My main blog, speedofcreativity.org, had been down for two weeks with a 503 error. Working with Claude as a troubleshooting partner, one command at a time, we traced the problem to a single configuration file that the server’s nightly maintenance was quietly setting aside as “invalid.” Once we understood the mechanism, the fix took one command, and it has held ever since. Then came the larger job: Seventeen of my domains and subdomains depended on that old server just to tell the Internet where they live, so we exported every DNS zone, cleaned out years of junk records, and rebuilt them on Cloudflare. I would have NEVER known to use Cloudflare for DNS migrations or been able to pull off all this troubleshooting and website repair from the command line / terminal without AI assistance.
Along the way we caught records the server had lost track of, including my Home Assistant remote address and the summer camp website my spouse and I used last year. Right before bedtime a crawler on Amazon’s cloud started hammering two small sites, spawning a new process for every request until the database was killed. Claude found the source IPs in my server logs, and helped me stop the runaway processes and block the whole address range at the firewall. Sites were back in under five minutes.
This morning I wanted to tell this story as a short video to my middle school web design students, so I asked Claude for a 60 to 90 second narration script and a detailed prompt for an AI video generator. Then I tried Google Vids for the first time. My first attempt used the Storyboard feature (File, then Storyboard), and I was not happy with the result. My second attempt used “Docs to Video,” pointing Vids at a Google Doc containing the script, and that one was good: On-screen text that matched the AI narration, it had reasonable pacing, and it included background music from the built-in library. For a tool I had only opened once before, going from script to a usable animated video in a few minutes was a very positive second experience.
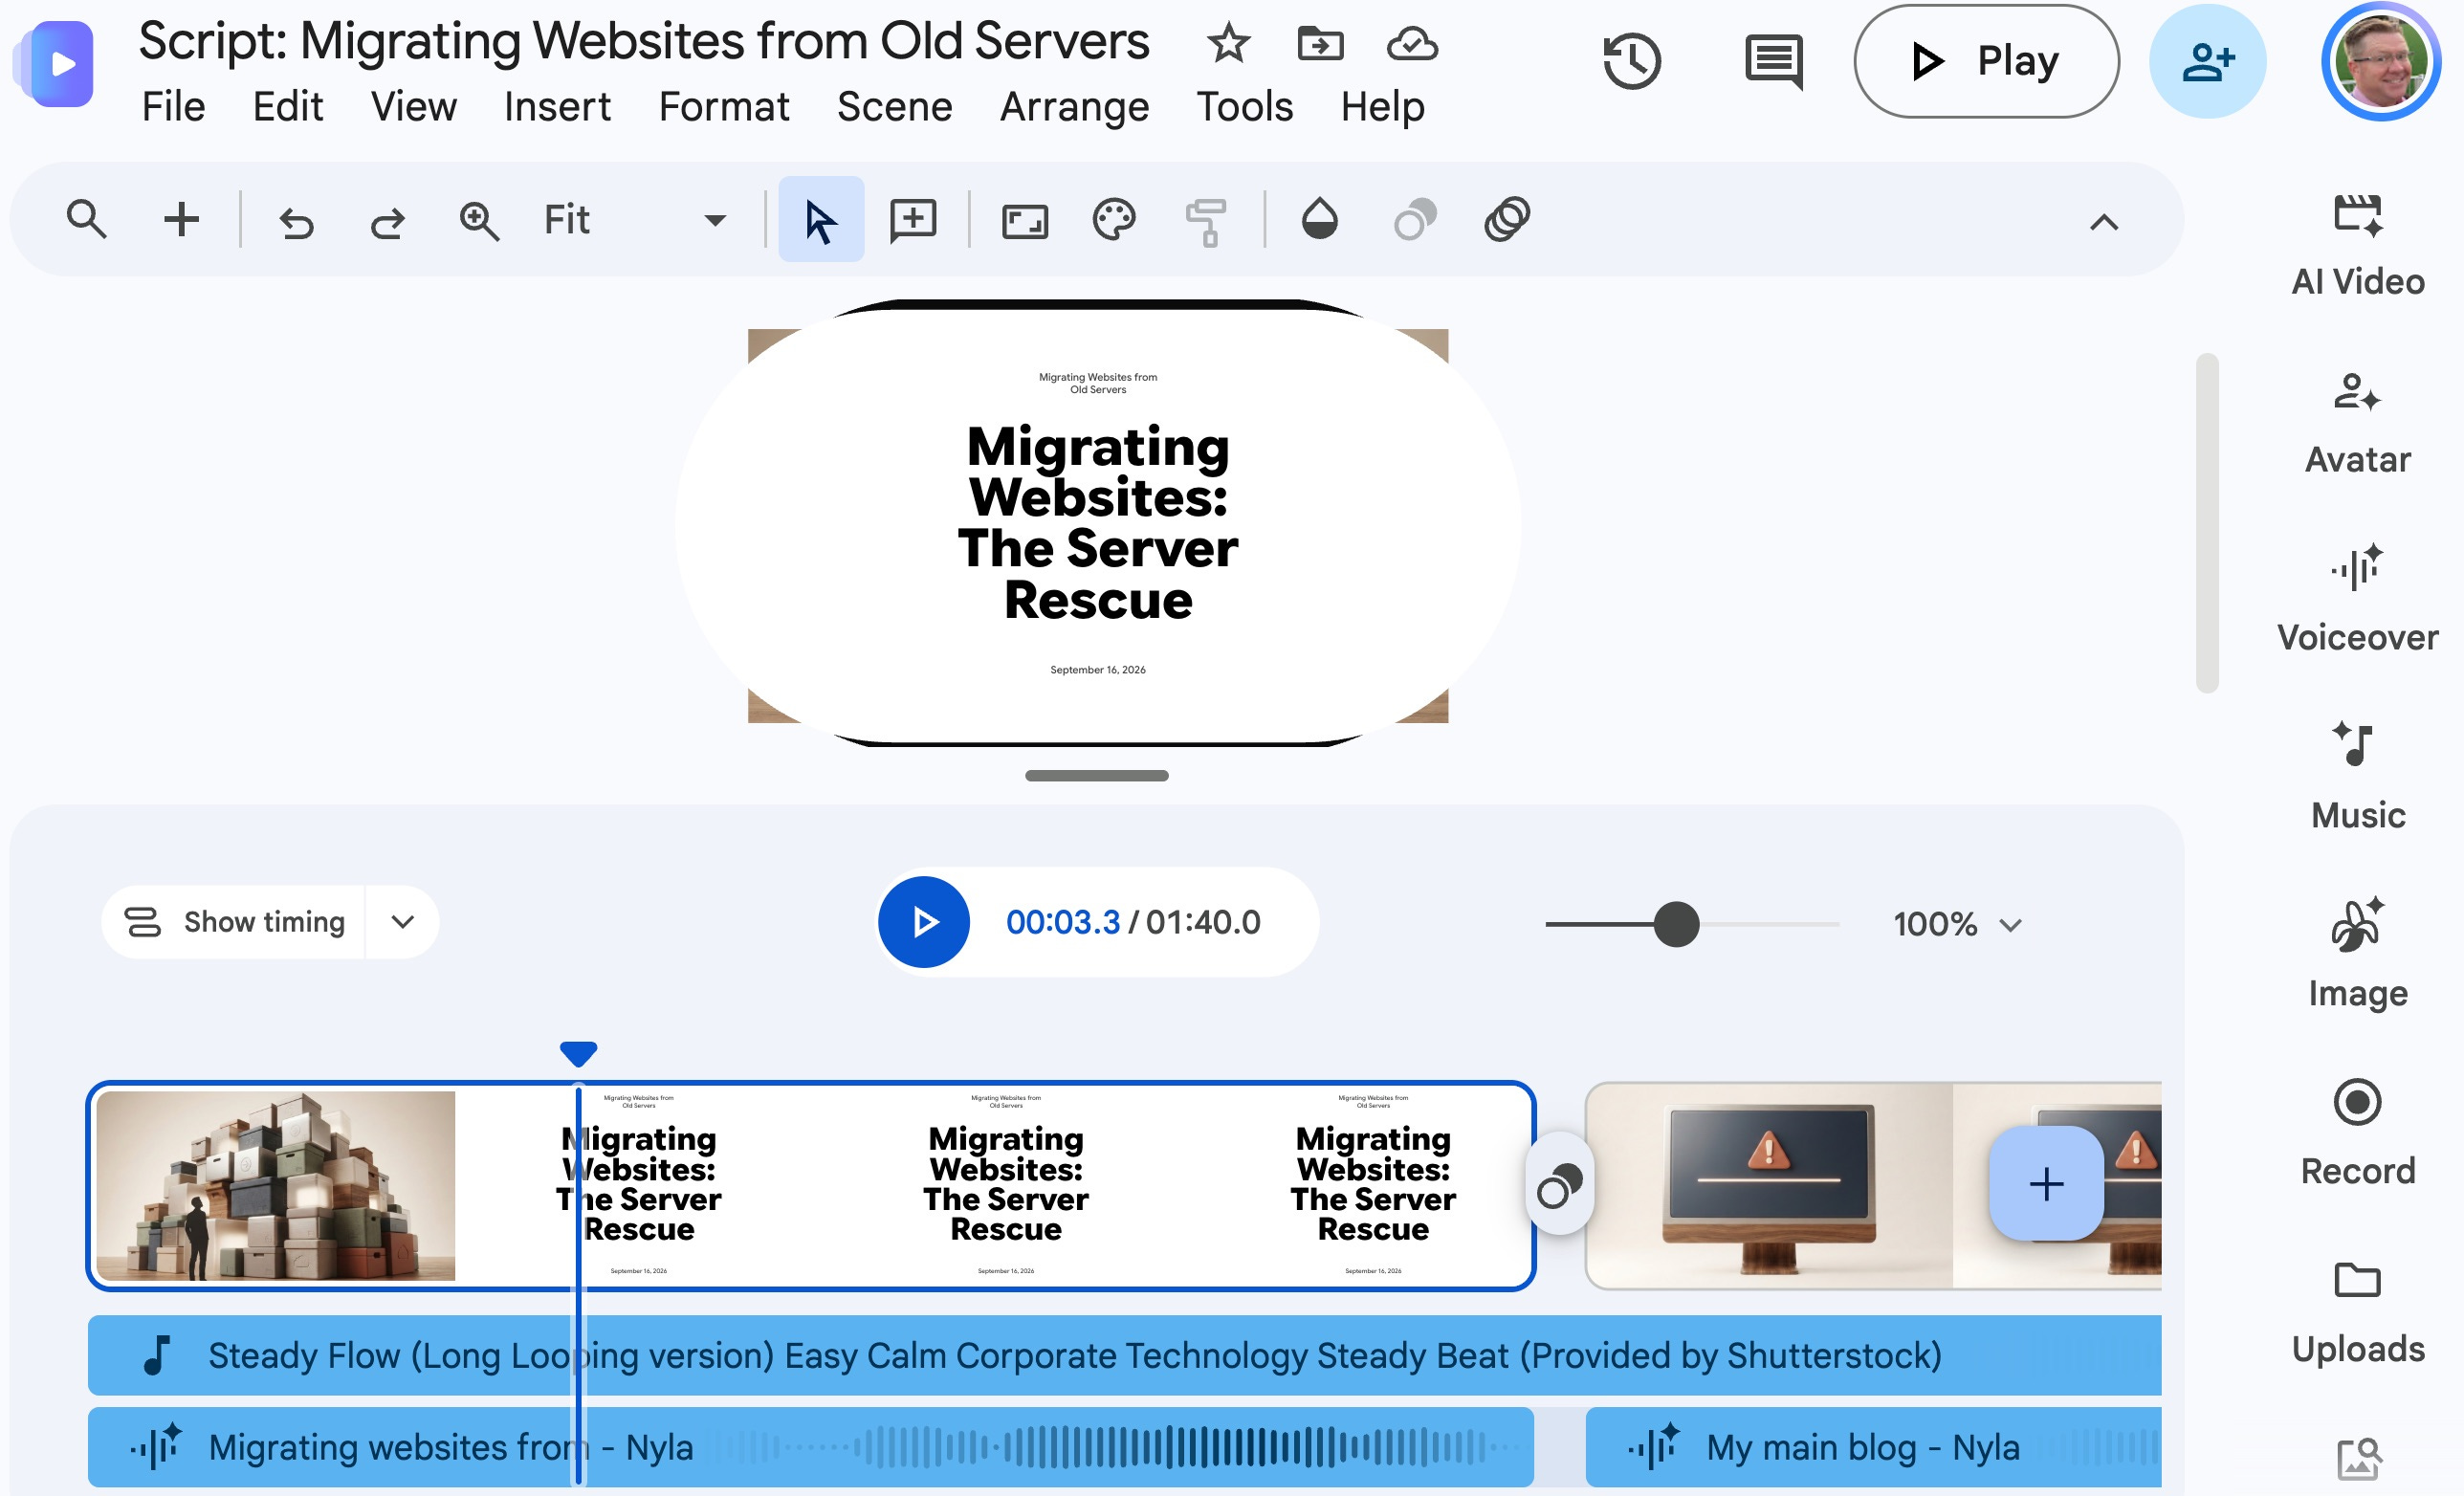
I did not want to post a purely AI-generated video, though, without attribution and some explanation. So:
I recorded a short selfie intro on my iPhone.
Exported the audio with MacOS’ QuickTime Player.
Ran it through Adobe Podcast Enhance Speech to clean up the background noise.
Swapped the enhanced audio back onto the intro clip in QuickTime.
Then appended the Vids video to the end and uploaded the combined file to YouTube.
I’ve included this video in this SubStack post, and also shared it on YouTube. The whole production, from script to published video, took about 20 minutes, which is REMARKABLE given the quality of the result.
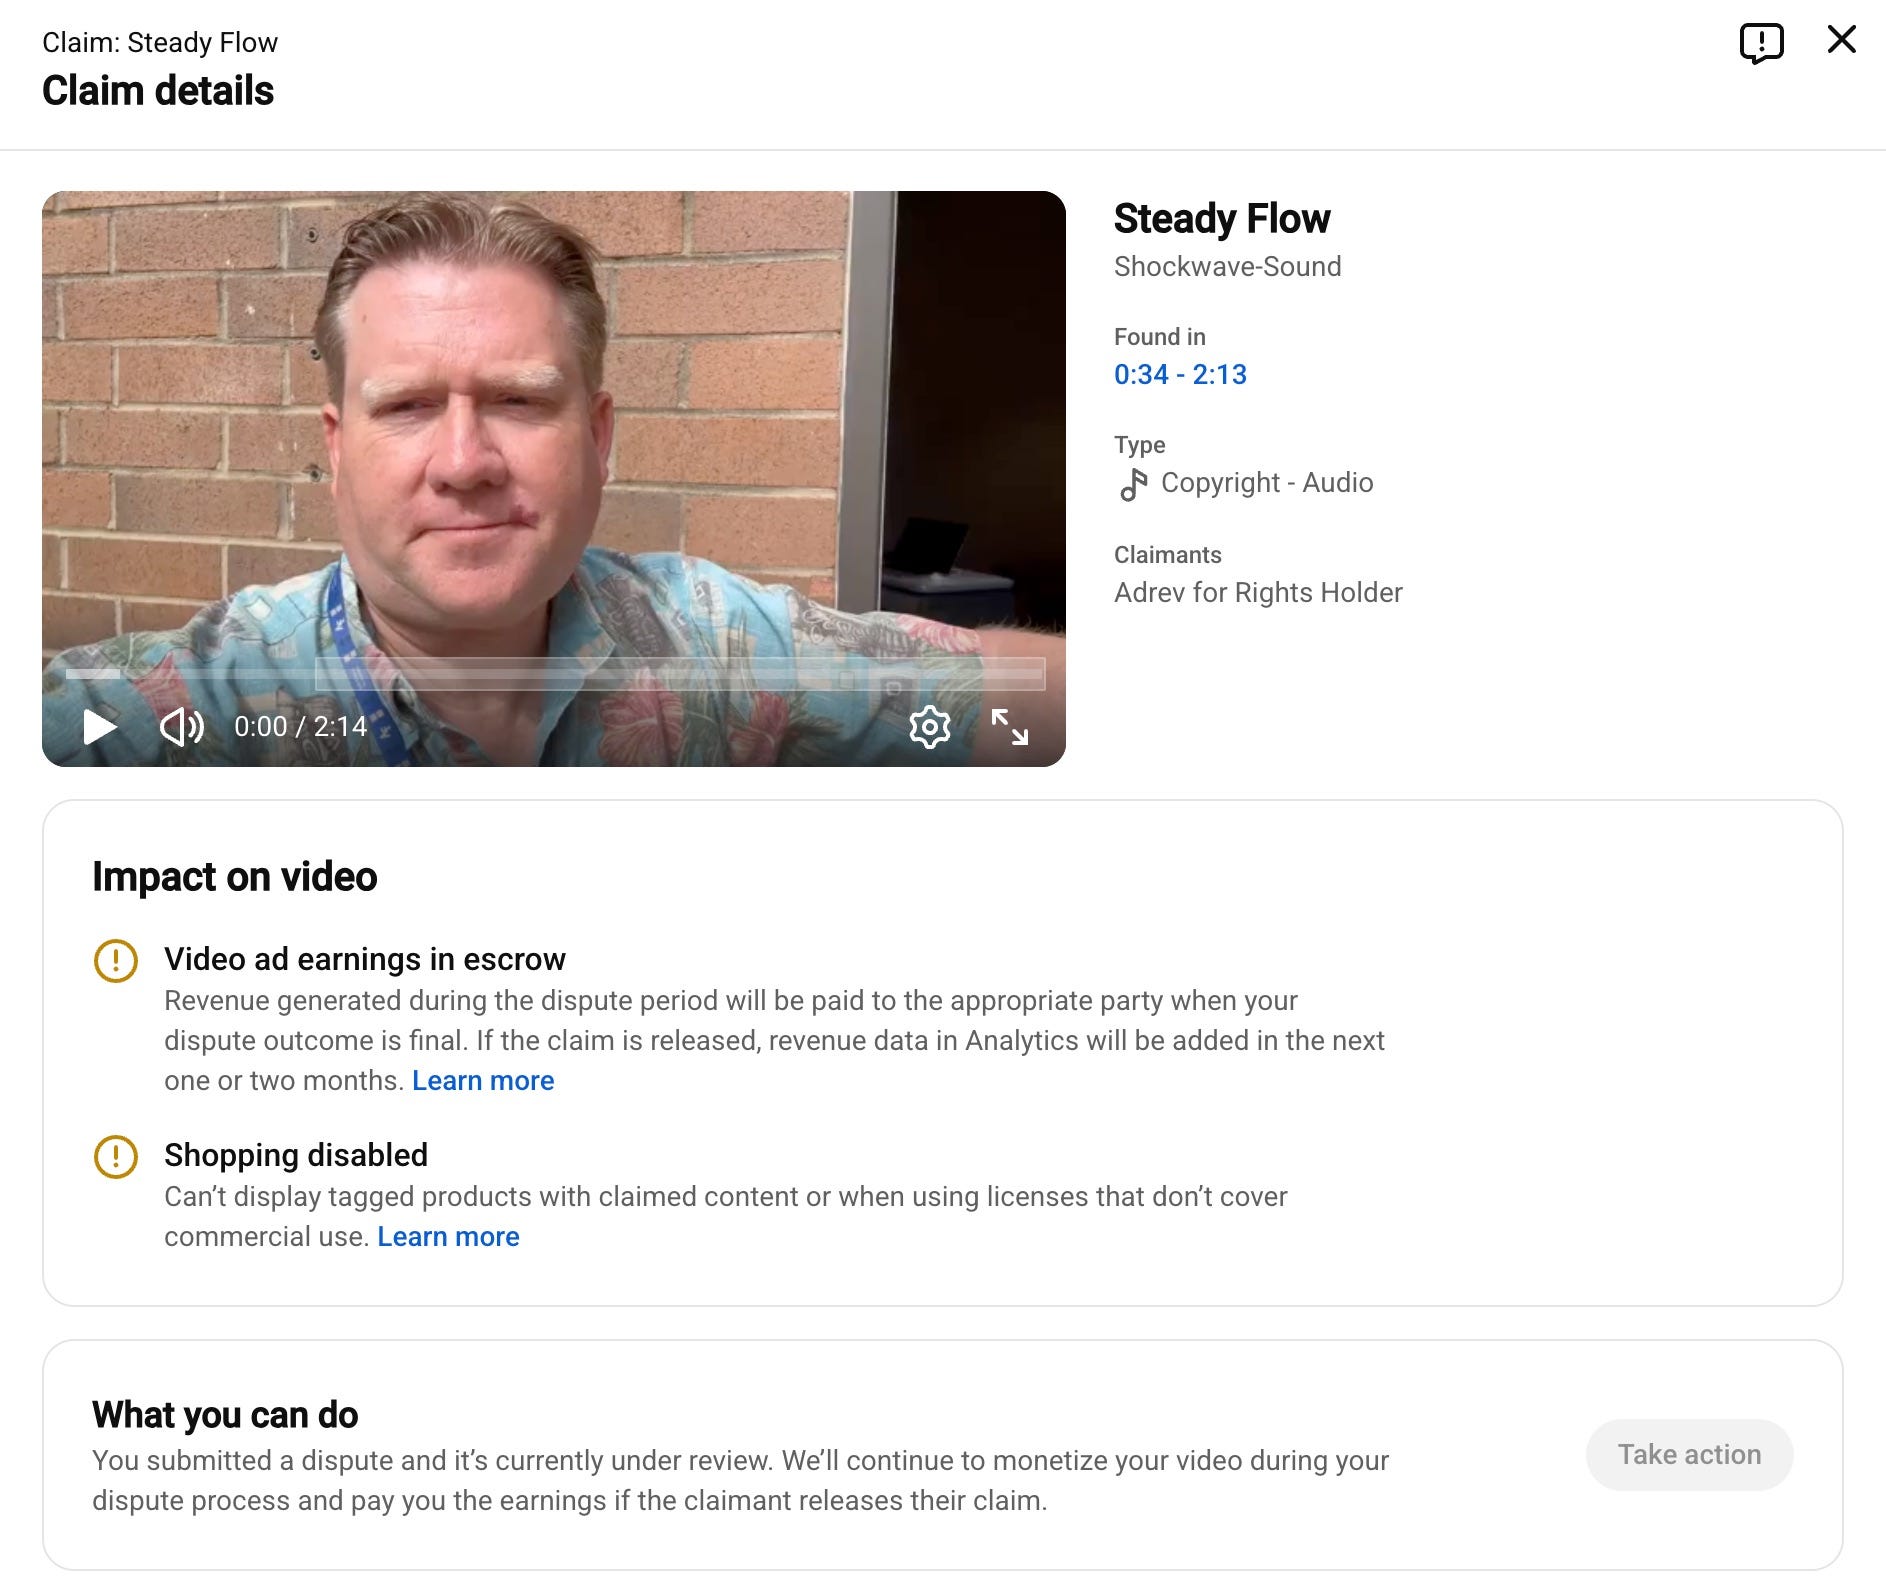
Then the surprise. I turned on monetization, and right away YouTube’s Content ID system flagged the video with a copyright claim on the background music, a track called “Steady Flow” from a stock music company, filed through a rights-management firm. The claim covered exactly the portion of the video that Google Vids had generated. In other words, the music Google itself placed in my video, from its own licensed library, was being claimed by a third party the moment the video went public. If you have not seen this before, YouTube has a plain explanation of how Content ID works and what a claim means. The short version: Content ID is an automated fingerprint matcher. It has no idea whether you hold a license. It only knows that the audio matches something in a claimant’s catalog.
I have run into this before, when a company claimed ownership of music that was in the public domain or openly licensed, and I have learned not to let it slide. I filed a dispute under the “License” reason, checked the box affirming I have permission from the copyright owner, and submitted this rationale, which Claude drafted and I reviewed:
The audio track “Steady Flow” in this video was not obtained from the claimant or any third party. It was provided directly by Google as part of the built-in, licensed stock music library inside Google Vids (vids.google.com), the Google Workspace application I used to create and export this video on September 16, 2026. Google licenses the music in that library for use in videos created with Google Vids, including publication to YouTube, and the track was applied from within the application itself. The claimant’s Content ID reference appears to match a stock track that Google has licensed for exactly this purpose. I did not upload, edit, or source the track independently. Under the terms of Google Vids and the Google Workspace Terms of Service, my use of this track is licensed. I am asking that this claim be released. I am happy to provide the Google Vids project link or export metadata on request.
The claimant now has 30 days to respond. If they do nothing, the claim is released automatically; in the meantime any ad revenue sits in escrow. I will update this post with the outcome. What strikes me is the absurdity of the loop: Google licenses a track, Google’s video tool inserts it, Google’s video platform flags it, and the burden of proof lands on the content creator. YouTube Content ID abuse is well documented and unfortunately common.
A few lessons, then, for anyone teaching or practicing media literacy in 2026.
First, “licensed” does not mean “claim-proof”; Keep a record of where every asset in your video came from, because you may need to explain it.
Second, automated copyright enforcement is a media literacy topic in its own right, worth teaching alongside source evaluation, because students can meet it the first time they upload anything to a public video sharing or social networking site.
Third, AI tools are now good enough to be useful for real work, from diagnosing a server at 11 PM to producing a video before class. The human in the loop should still read the logs, check the facts, add their own face and voice, and stand behind the result with a signature. I’m trying to do those things in this example.
If you have had a similar experience with Content ID and licensed music on YouTube, I would like to hear how it resolved. I’d also love to hear what your experiences have been with Google Vids, or other AI video generation tools. I’m concerned about the era of “AI video slop” we’ve quickly entered… but I also see positive potential for teachers and storychasers like yours truly.
* AI Attribution: I used Claude AI to help me draft this article / blog post, which I thoroughly reviewed and edited further before sharing.


